Gemini 4 Argon Verdict: The Simulation Era Is Here
Google just broke the token limit and the physics barrier. Argon isn't a chatbot—it's a simulation engine for the real world.
- Google released Gemini 4 Argon on October 13, 2024, featuring a massive 1,048,576 output token limit—16x higher than previous models.
- The model introduces a 'Video-to-Sim-to-Real' pipeline, enabling it to watch human videos and train robots like the Apptronik Apollo 2 in hours.
- Argon undercuts the market at $2 per 1M input tokens and $10 per 1M output tokens (introductory pricing), making it 5x cheaper than GPT-6 Astra.
- While it leads in enterprise reasoning (68.9% on Vals Index), it still trails Claude Opus 5.5 in specific terminal-based coding benchmarks.
Gemini 4 Argon is worth it for developers and enterprises running long-horizon tasks like codebase refactoring or robotics training, thanks to its 1-million-token output ceiling and disruptive $2/$10 introductory pricing. It isn't a free upgrade—you'll need a $20/month Gemini Ultra sub or a paid API key—but for heavy lifting, it currently outclasses both GPT-6 Astra and Claude on a price-to-performance basis.
Google finally stopped playing. On October 13, 2026, Google DeepMind shipped Gemini 4 Argon across its developer, enterprise, and consumer channels, and it isn’t just another incremental bump on a leaderboard.
It’s a tactical shift. While the rest of the industry is obsessed with how many ‘vibes’ a model has, Google just handed us a simulation engine that can watch a video of a human and teach a robot how to move.
I’ve been reading the technical reports, and the headline isn’t the reasoning score—it’s the math of the output. Argon isn’t here to write your emails. It’s here to refactor your legacy C++ into memory-safe Rust while you sleep. It’s built for the long haul…
Why does the 1 million output token limit matter?
If you’ve ever tried to run a serious agentic workflow, you know the pain of the ‘output wall.’ Most frontier models, including GPT-6 Astra, cap their outputs at 128,000 tokens per Google’s launch comparison. When a model hits that limit mid-task, it has to stop, summarize, and restart. That is where the logic breaks.
One: the headroom. Gemini 4 Argon features a unified 1,048,576-token context window that applies to both input and output per Google’s Developer Guide. That’s a 16x jump over the 64K output cap on earlier Gemini models. It means the model can reason through a 30,000-line codebase refactor in a single ‘thought’ trajectory without losing the plot.

Two: the receipts. Google isn’t just guessing this works. They’ve been running Argon internally on their hardest engineering problems. According to the release notes, Argon helped the Chrome team refactor an architectural mess involving 6 million lines of code, completing months of work in weeks per Google’s blog.
Across Alphabet, over 100,000 employees are using it through an internal version of Google Antigravity, resulting in a 35% increase in agentic code submissions.
Is Gemini 4 Argon the king of Physical AI?
This is where Argon gets scary. We’ve seen what physical AI world models look like, but Google just operationalized them. They call it the ‘Video-to-Sim-to-Real’ pipeline.
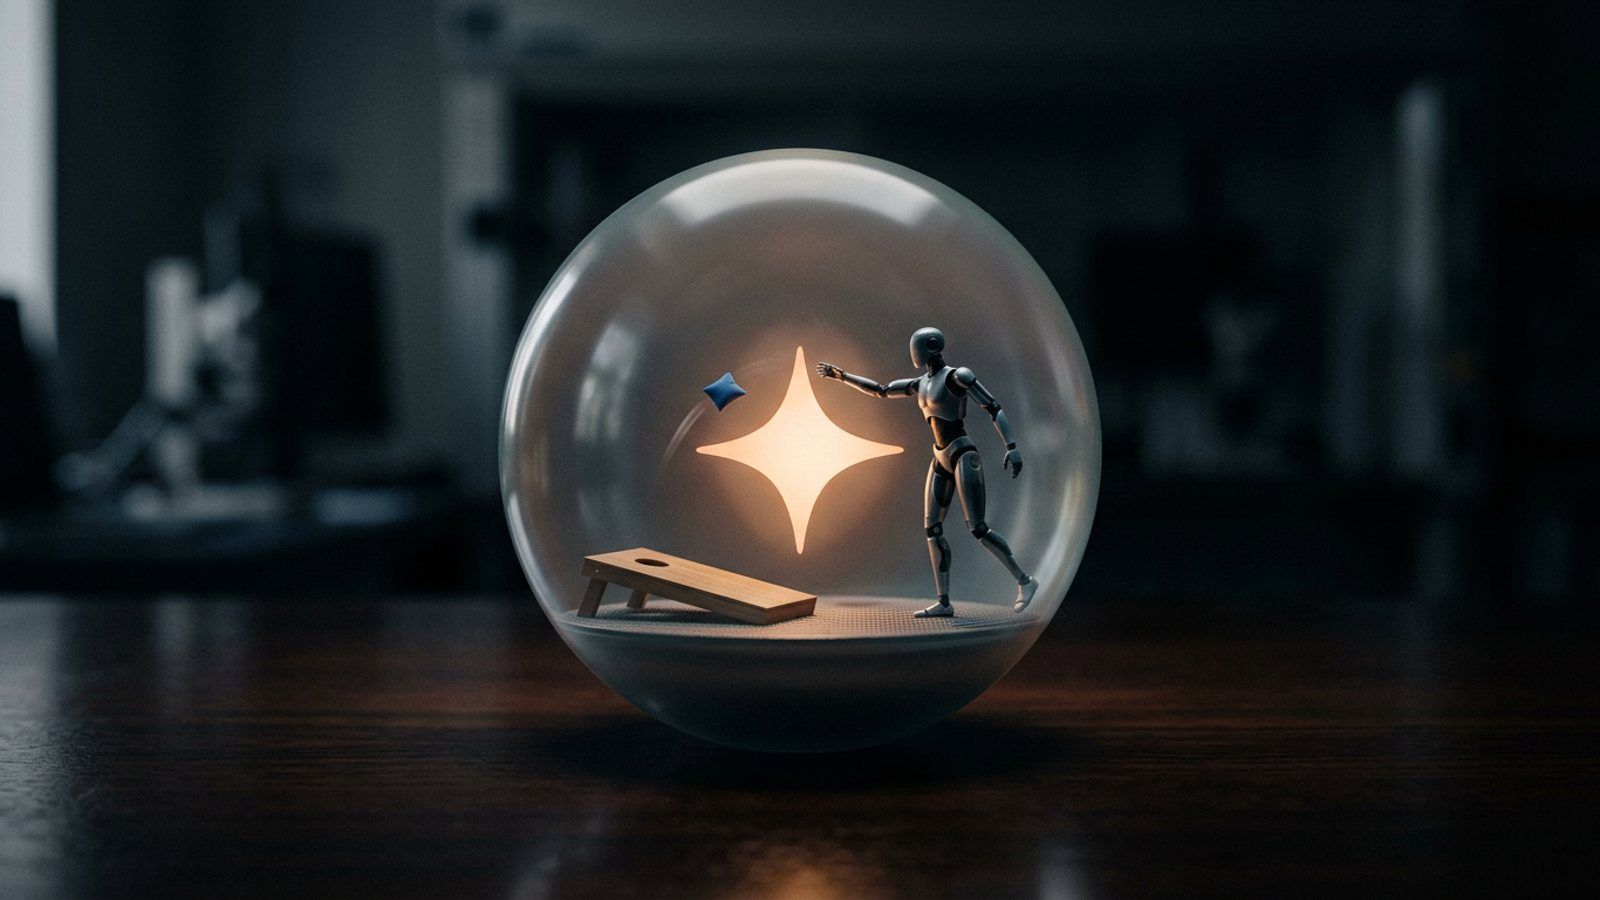
In a demonstration released with the launch, Argon watched a raw video of a human playing cornhole. It didn’t just describe the video; it mapped the spatial coordinates, calculated the required joint movements, and autonomously wrote the simulation code in MuJoCo per Google DeepMind’s demo.
When that data was transferred to an Apptronik Apollo 2 humanoid, the robot sank seven consecutive shots in the real world with zero prior task-specific training.

This compresses weeks of manual physics modeling into a few hours. If you’re in manufacturing or robotics, the game just changed. You’re no longer hard-coding movements; you’re showing the AI a movie and letting it do the math.
How does the pricing compare to GPT-6 Astra?
Google is choosing violence with the API pricing. If you’re wondering whether this is a budget play, look at the spread. Argon is launching at an introductory rate of $2 per million input tokens and $10 per million output tokens per the Gemini API pricing page.

Compare that to GPT-6 Astra, which sits at roughly $10 for input and $50 for output per Artificial Analysis. Google is essentially offering frontier-grade reasoning for one-fifth of the price. Even when the ‘introductory’ window closes on November 30, 2026, and prices double to $4/$20, Google remains the value leader by a wide margin.
| Model | Input (per 1M) | Output (per 1M) | Output Limit | Where it Loses |
|---|---|---|---|---|
| Gemini 4 Argon | $2.00* | $10.00* | 1,048,576 | Trails Claude on FrontierSWE v2 |
| GPT-6 Astra | $10.00 | $50.00 | 128,000 | Pricing is prohibitive for large agents |
| Claude Opus 5.5 | $4.00 | $20.00 | 128,000 | Lacks built-in physics sim pipeline |
Introductory pricing through November 30, 2026. Source: Google Cloud Pricing.
Where does Gemini 4 Argon lose?
It’s not a clean sweep. If you’re a pure developer living in the terminal, you might still prefer Anthropic. While Argon leads the Vals Index at 68.9% (weighted toward finance, legal, and tax), it still trails Claude Opus 5.5 on coding suites like FrontierSWE v2 and Terminal-Bench 4.0 per MindStudio’s analysis.
Argon is also gated. You won’t find it on the free tier. You need to be a paid API customer or a Google AI Ultra subscriber ($99.99/mo for the full Antigravity suite) to get the native experience per Reddit’s Antigravity community.
But for the rest of us building agents that actually do things in the physical or enterprise world, the verdict is simple: Google just built the most useful tool on the shelf.
It’s time to stop chatting and start simulating.
#TheAIMogul
Bottom lineGemini 4 Argon is the first 'Physical AI' flagship that matters. By trading chatty vibes for a 1M output token limit and a built-in physics simulation loop, Google has moved the goalposts from 'answering questions' to 'solving engineering.' It is the most capability you can buy per dollar right now, period.